PRODUCTION
I build AI systems
that hold up in production.
RAG chatbots that cut support load by 25%. Airflow pipelines running at 99.9% reliability. I design and ship data + AI infrastructure that doesn't break under real workloads.
Saran Jaya Thilak
Data Engineer & GenAI Specialist
About Me
I engineer data
and AI systems
that scale.
I spent nine years keeping mission-critical infrastructure alive — first at Nokia, then at Huawei — managing telecom and cloud systems at 99.9%+ uptime, 24×7, with no tolerance for failure. That decade of operational discipline shaped how I think about reliability, observability, and what "production-ready" actually means.
Now, with an M.Sc. in Data Science and hands-on work at Tesla building RAG chatbots and Airflow pipelines, I bring that same infrastructure mindset to AI engineering. I build GenAI and data systems the way I once ran networks — with the assumption that they have to hold up under real load, not just in a notebook.
Experience
A decade of building.
Tesla
Data Engineer
University of Europe for Applied Sciences
M.Sc. Data Science
Huawei
Cloud Support Engineer
Huawei
Operations Team Leader
Nokia
Operations & Maintenance Engineer
My Expertise.
ACTIVE SYSTEM INSPECTOR / 01
Production Data Engineering
Built for high-throughput, zero-data-loss ingestion at scale. Designing ultra-reliable, petabyte-scale ETL/ELT pipelines with Apache Airflow & dbt — automated data contracts, strict idempotency, and streaming ingestion into Snowflake & BigQuery.
STATUS: OPERATIONAL
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- ETL/ELT design
- Streaming ingestion
- Data contracts
- SQL transformations
TOOLS & TECHNOLOGIES
- Airflow
- dbt
- BigQuery
- Snowflake
- ETL/ELT
ACTIVE SYSTEM INSPECTOR / 02
Enterprise GenAI & RAG Systems
Hybrid retrieval with grounded, citation-backed responses. Building enterprise-grade GenAI & RAG platforms with sub-second latency, semantic + keyword search fusion, and robust hallucination guardrails using LangChain, FAISS, and cross-encoder reranking.
GROUNDING: VERIFIED
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- Hybrid retrieval
- Multimodal embeddings
- Citation grounding
- Hallucination guardrails
TOOLS & TECHNOLOGIES
- LangChain
- Vector DB
- FAISS
- Guardrails
- Reranking
RELATED PROJECT EXAMPLES
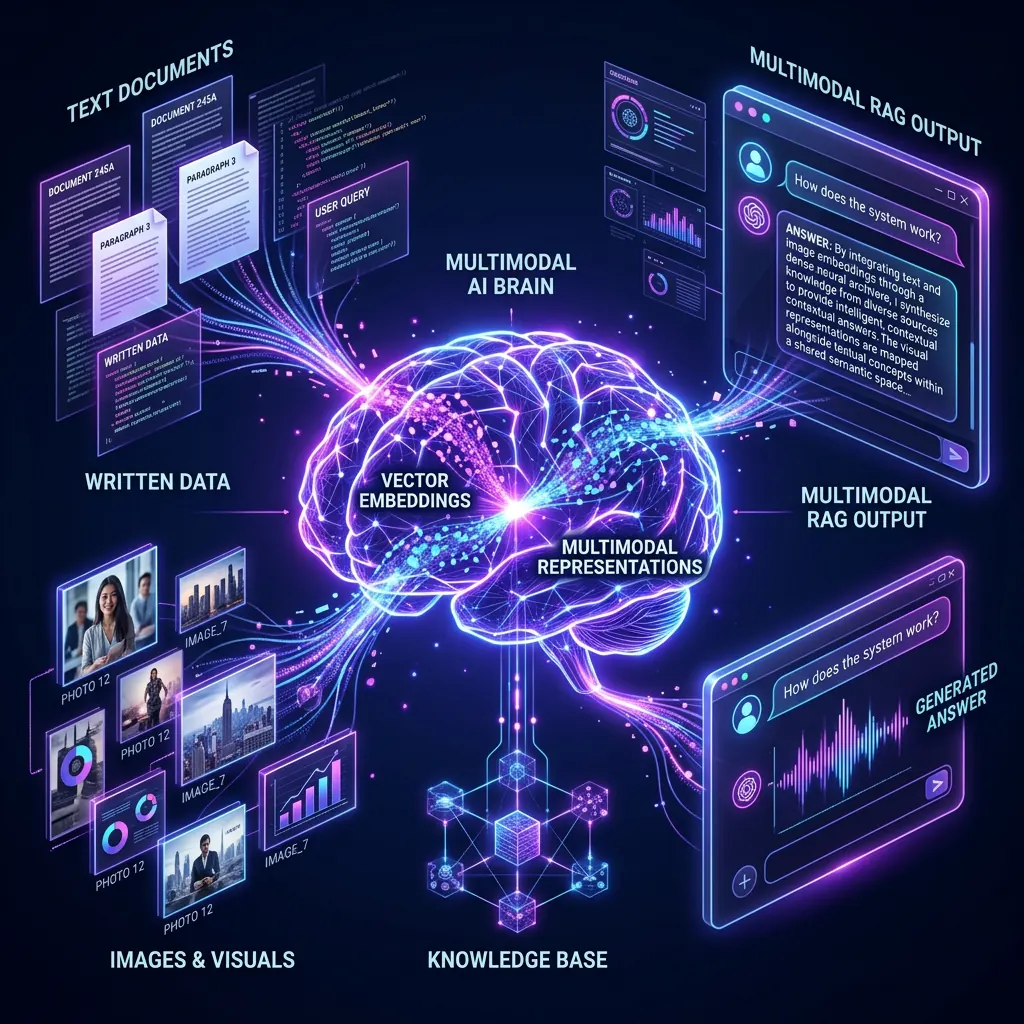 Multimodal RAG SystemProduction RAG + Conversational AIA production-ready Multimodal Retrieval-Augmented Generation system that supports conversational querying over text and image data. Handles chunking, embedding, reranking, and grounded LLM responses with citation traces — designed for real deployment, not demos.
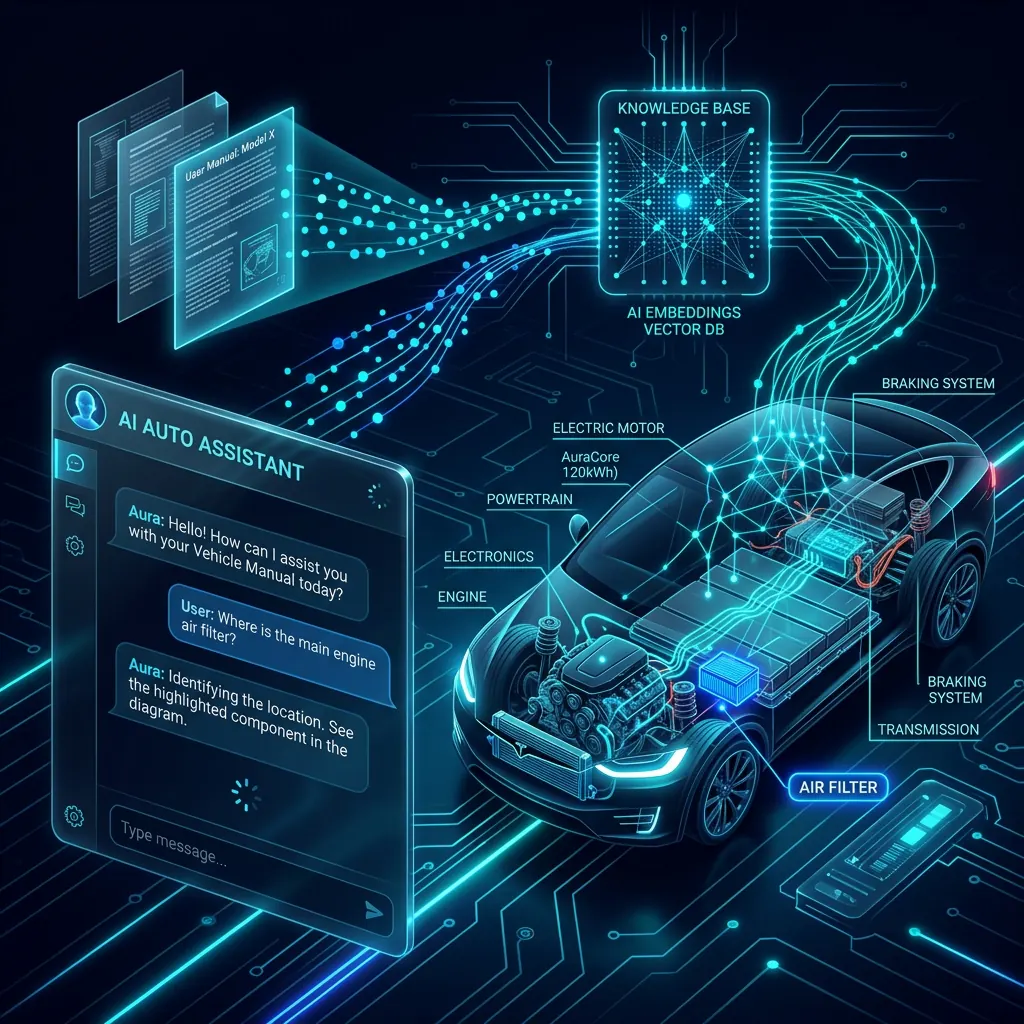 Car Manual RAG AssistantClosed-Domain PDF QADomain-specific RAG over a single corpus of automotive PDFs. A focused proof-of-concept for constrained document QA — no multimodal retrieval, no general-purpose chat, just precise grounded answers from a closed source.
ACTIVE SYSTEM INSPECTOR / 03
Production MLOps & Model Serving
Low-latency inference with canary rollout and drift monitoring. Operating ML model serving pipelines with zero-downtime deployments, real-time drift detection, and quantized inference via NVIDIA Triton, MLflow, and FastAPI.
ROLLOUT: CANARY ENABLED
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- Model serving
- Quantized inference
- Canary deployments
- Drift monitoring
TOOLS & TECHNOLOGIES
- MLflow
- Triton
- Quantization
- Docker
- Model Registry
ACTIVE SYSTEM INSPECTOR / 04
Cloud Topology & IaC
100% declarative, multi-cloud ready. Provisioning secure, cost-optimized infrastructure with Terraform & Kubernetes — battle-tested across Tesla, Huawei, and Nokia for 99.99% availability.
ORCHESTRATION: 100% DECLARATIVE
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- Infrastructure as code
- Multi-cloud provisioning
- Container orchestration
- Cost optimization
TOOLS & TECHNOLOGIES
- Terraform
- AWS
- GCP
- Kubernetes
- FinOps
RELATED PROJECT EXAMPLES
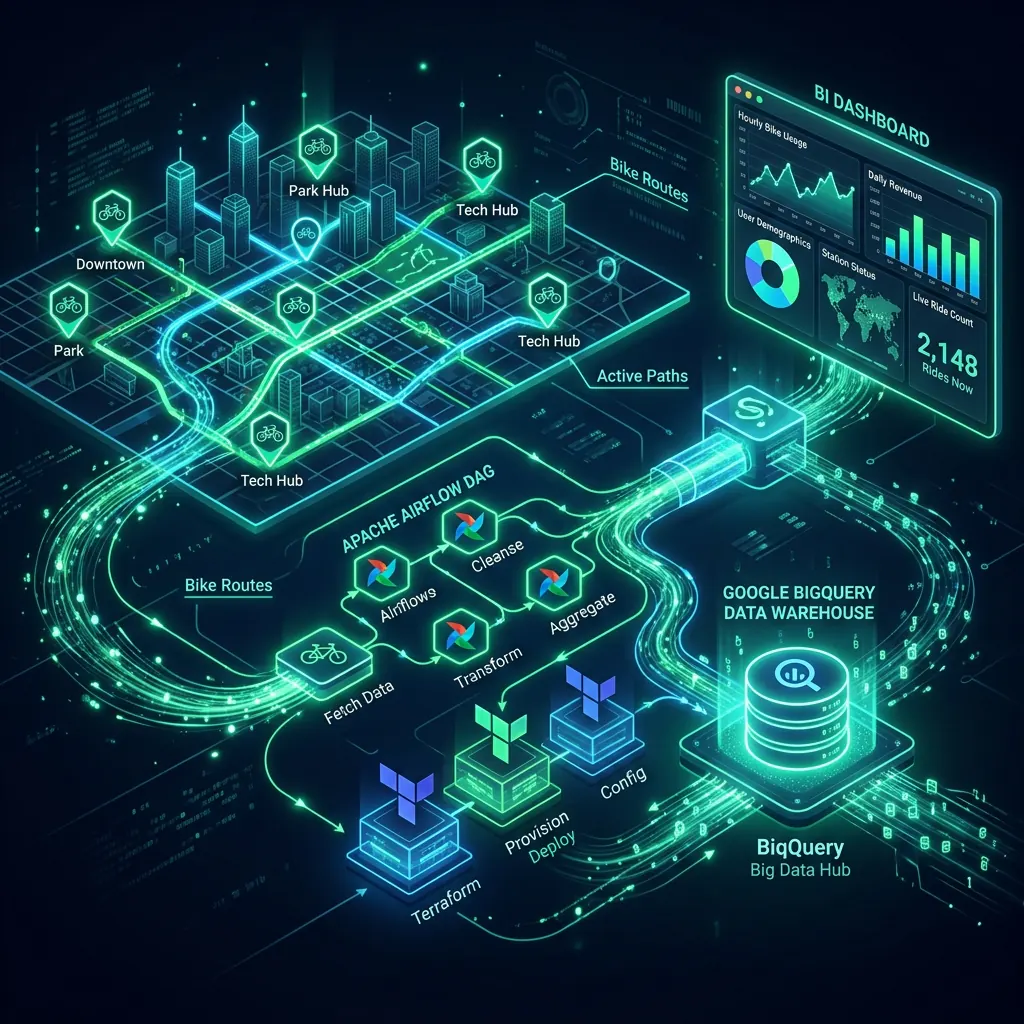 Divvy Bikes – End-to-End Data PipelineGCP | Terraform | Airflow | DBTBuilt an end-to-end data pipeline on GCP using Terraform for infrastructure, Airflow for orchestration, and DBT for SQL transformations. Loaded data into BigQuery and visualized insights via Google Data Studio.
 Vanilla Steel AssessmentFull-stack | APIs | DockerA full-stack assessment project demonstrating modern software engineering practices, including backend development, APIs, testing, containerization, and deployment.
ACTIVE SYSTEM INSPECTOR / 05
Mission-Critical Ops & High Availability
High-availability operations with self-healing failover design. 5+ years directing enterprise NOC & telecom backbones — automated failovers, real-time Prometheus/Grafana telemetry, and circuit-breaker remediation at scale.
AVAILABILITY: SELF-HEALING
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- Incident response
- Failover design
- SLA operations
- Infrastructure monitoring
TOOLS & TECHNOLOGIES
- High Availability
- Prometheus
- Grafana
- Incident SRE
- Failover
ACTIVE SYSTEM INSPECTOR / 06
Full-Stack AI Interfaces
Real-time token streaming over WebSocket with async microservices. Bridging AI backends with reactive client apps via FastAPI, type-safe React/Next.js frontends, and low-latency WebSocket streaming pipelines.
STREAMING: REAL-TIME
deployment: zero-downtime
guardrails: enabled
RELATED SKILLS
- Reactive interfaces
- Async APIs
- Token streaming
- Type-safe development
TOOLS & TECHNOLOGIES
- FastAPI
- React
- Next.js
- TypeScript
- WebSocket
RELATED PROJECT EXAMPLES
 German Learning AppTypeScript | AI Tutor | A1–C1AI-powered German learning platform with interactive lessons, vocabulary practice, pronunciation support, quizzes, and personalized learning from A1 to C1.Vanilla Steel AssessmentFull-stack | APIs | DockerA full-stack assessment project demonstrating modern software engineering practices, including backend development, APIs, testing, containerization, and deployment.
Featured Dashboard.
A curated selection of my most significant technical achievements, architected for performance and scale.
Multimodal RAG System
A production-ready Multimodal Retrieval-Augmented Generation system that supports conversational querying over text and image data. Handles chunking, embedding, reranking, and grounded LLM responses with citation traces — designed for real deployment, not demos.
Tech Stack
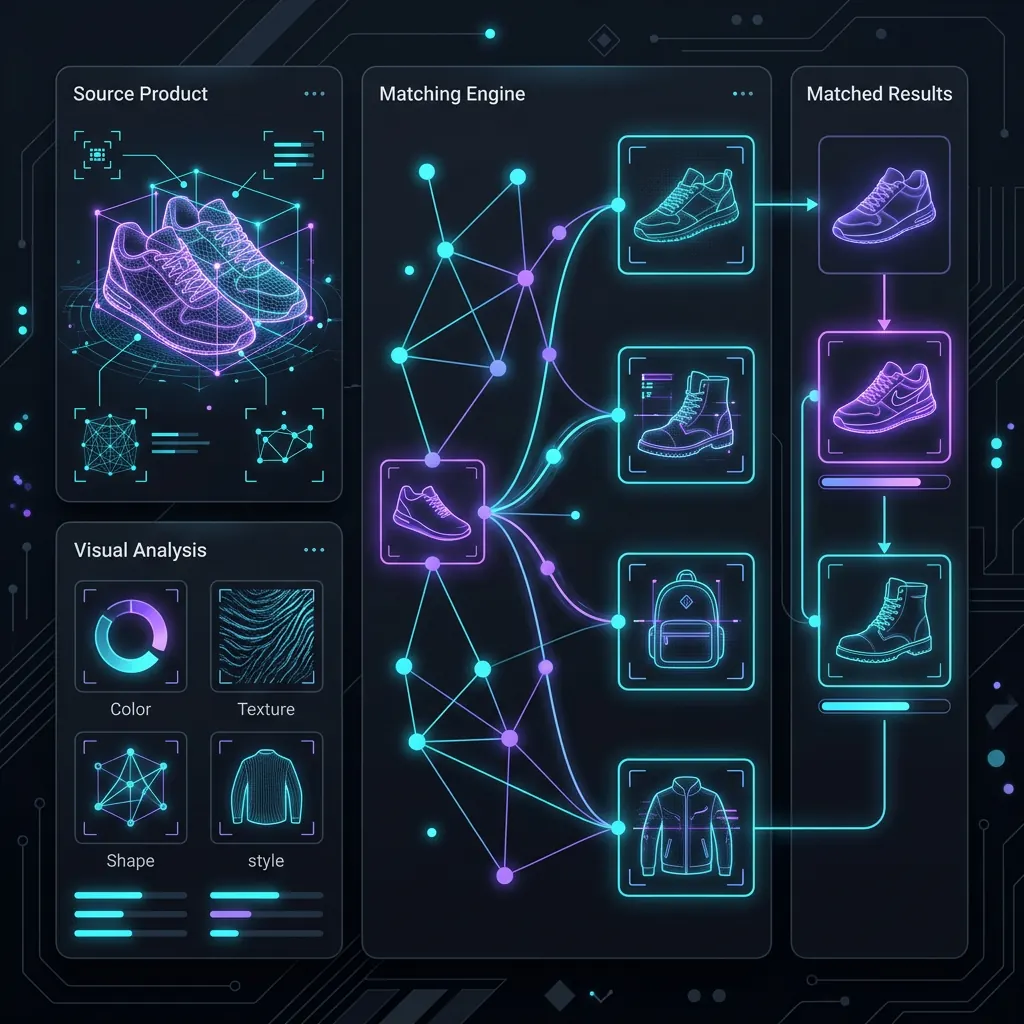
AI Product Matching System
Developed an image-based product search engine using FAISS for vector similarity and a quantized CLIP model served via NVIDIA Triton Inference Server. Integrated MongoDB and Docker for fast, scalable product matching.
Tech Stack
Car Manual RAG Assistant
Domain-specific RAG over a single corpus of automotive PDFs. A focused proof-of-concept for constrained document QA — no multimodal retrieval, no general-purpose chat, just precise grounded answers from a closed source.
Tech Stack
Divvy Bikes – End-to-End Data Pipeline
Built an end-to-end data pipeline on GCP using Terraform for infrastructure, Airflow for orchestration, and DBT for SQL transformations. Loaded data into BigQuery and visualized insights via Google Data Studio.
Tech Stack
More Projects
German Learning App
AI-powered German learning platform with interactive lessons, vocabulary practice, pronunciation support, quizzes, and personalized learning from A1 to C1.
GitHub Contributions.
Shipping code consistently — building in public, one commit at a time.
My Certifications.
AWS Certified Solutions Architect
OCI 2025 Certified Generative AI Professional
OCI 2025 Certified AI Foundations Associate
LangChain Application Development
Terraform Basics
SQL for Data Science
Published work.
Peer-reviewed machine learning research published at IEEE — spanning renewable energy forecasting and dynamic pricing systems.
Performance Ratio Estimation of Solar Power Plants Using Machine Learning Algorithms
Applied advanced machine learning models to estimate the performance ratio of solar PV plants using operational and environmental data. Among tested algorithms, Random Search CV Regression achieved the highest accuracy with an R² of 0.93 and minimal error. Results highlight the effectiveness of models like Random Search CV, AdaBoost, and Random Forest in optimizing solar plant performance and advancing efficient renewable energy solutions.
A Comparison Between Machine Learning Models for Air ticket Price Prediction
Explored machine learning techniques to predict airline ticket prices using two Kaggle datasets, addressing challenges from dynamic pricing fluctuations. Evaluated models including Random Forest and Randomized Search CV, with the proposed model providing accurate fare predictions. This solution supports travelers in making informed decisions by forecasting price trends from historical data.
Build.
Ship.
Scale.
I design and deliver production-grade RAG systems, end-to-end MLOps pipelines, and scalable cloud data infrastructure — built to handle real workloads, not just demos. If you have a data or AI problem worth solving, let's get to work.
- linkedin.com/in/saranjayathilak
- GitHub
- github.com/saranjthilak
- Calls
- Available for calls upon request